

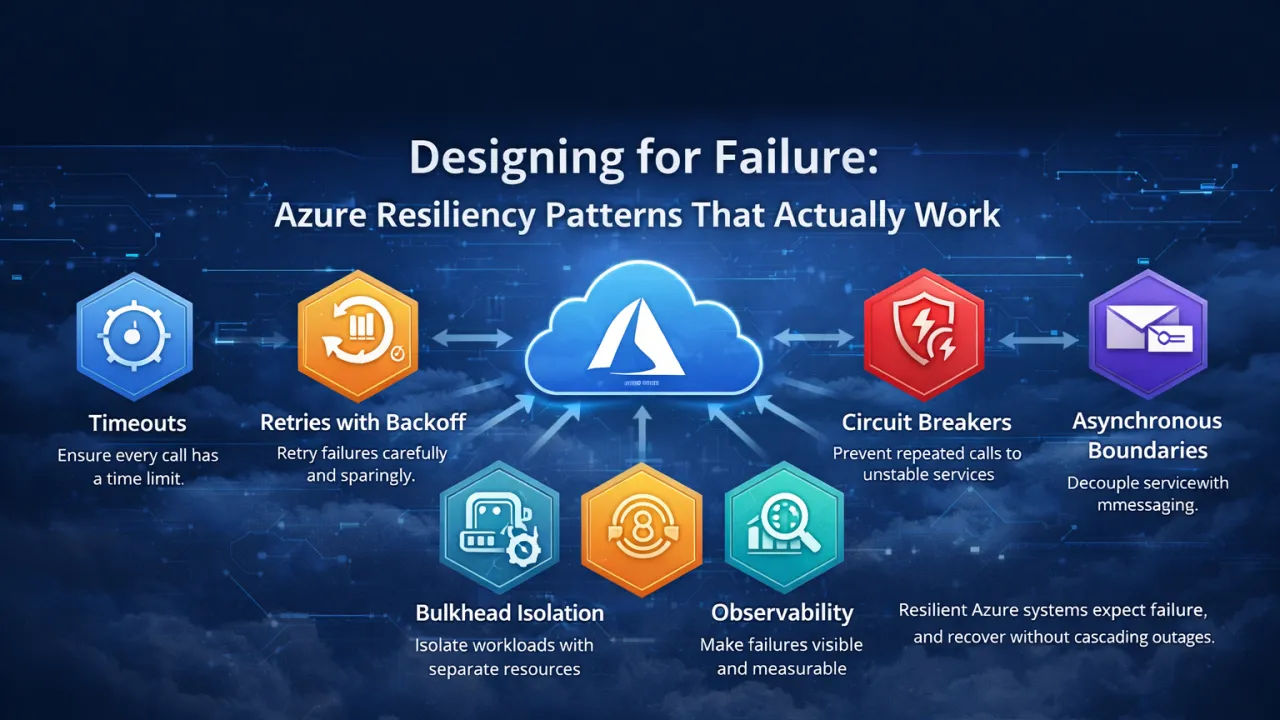
In cloud-native systems, failure is not an exception—it is a certainty. Azure provides highly available infrastructure, but no platform can eliminate network latency, transient faults, throttling, or dependency outages. The real difference between resilient and fragile systems lies in how applications are designed to respond when failures occur. Designing for failure means accepting that components will break and ensuring the system can absorb, isolate, and recover from those failures without cascading impact.
One of the most effective resiliency principles in Azure systems is failing fast with clear boundaries. Timeouts are not optional in distributed systems; they are essential. Without explicit timeouts, slow dependencies silently consume threads and resources until the system collapses under load. Well-designed Azure applications define strict timeout policies and treat delayed responses as failures, allowing the system to recover or degrade gracefully rather than stall indefinitely.
Retries are another powerful but frequently misused resiliency pattern. Blind or aggressive retries often amplify failures instead of resolving them, especially during partial outages. Resilient Azure systems apply retries selectively, using exponential backoff and jitter, and only for operations that are safe to repeat. Combined with circuit breakers, retries become a controlled recovery mechanism rather than a source of cascading failure.
Asynchronous communication is also a cornerstone of resilient design. Synchronous request chains tightly couple services and propagate failures instantly across the system. By introducing asynchronous boundaries—such as messaging or background processing—Azure systems can absorb spikes, decouple dependencies, and continue operating even when downstream services are unavailable. Failures become backlogs to process later, not immediate outages.
Isolation further strengthens resiliency by preventing one failing component from impacting others. Techniques such as bulkhead isolation ensure that critical workloads are protected from less important tasks. In Azure environments, this often means separating resources, queues, or compute for high-priority traffic so that non-essential failures do not degrade the entire system.
Finally, observability is what makes resiliency actionable. Without clear visibility into failures, retries, and degraded behavior, systems fail silently and unpredictably. Resilient Azure systems invest heavily in structured logging, distributed tracing, and meaningful alerts, enabling teams to detect issues early and respond before users are affected.
Designing for failure is not about pessimism—it’s about realism. Azure resiliency patterns work best when they are applied intentionally, consistently, and early in the design process. Systems that embrace failure as a design constraint don’t just survive incidents—they recover quickly, degrade gracefully, and earn long-term trust from both users and operators.